Free proxies can carry a Scrapy crawl of public pages, as long as the settings expect most of them to fail. We tested that on 28 September 2026 at 12:56 UTC. We took 300 free proxies that our list showed as alive. Through each, we made the request a new Scrapy project sends first to any site, the one for its robots.txt, here on our own site. 83 returned the real file. 146 never accepted the connection, and each of those held its request for more than two minutes.
This page covers what the test showed, the settings and the middleware that follow from it, SOCKS5 entries, and what a free proxy should never carry.
What happened to 300 requests
For an https:// page, Scrapy asks an HTTP proxy for a tunnel with the CONNECT method. RFC 9110 describes that as a request to "establish a tunnel to the destination origin server". TLS then runs inside the tunnel, so the proxy passes the bytes on without reading them, unless it swaps the certificate. Our test did the same, with the user agent of a default Scrapy request, and gave each request 180 seconds, the default of Scrapy.
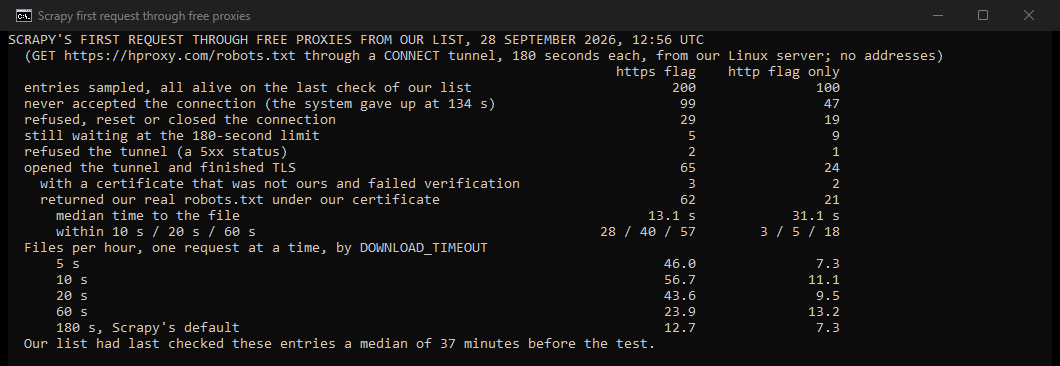
- About half never answered. 146 of the 300 entries never accepted the connection. Scrapy would wait 180 seconds, but on our Linux server the operating system gave up first, after 134 seconds each. The Linux kernel documentation puts that limit at 131 seconds by default.
- The https flag matters. Our list gives the flag to a proxy that opened a CONNECT tunnel to our checker. With the flag, 62 of 200 returned the file, at a median of 13.1 seconds. Without it, 21 of 100 did, at a median of 31.1 seconds.
- Five certificates were not ours. Of the 89 proxies that finished TLS, 5 handed back a certificate that was not ours and failed verification. One gave its issuer as mitmproxy. That is an open-source tool whose certificate authority, in its own documentation, "is used for on-the-fly generation of dummy certificates for each visited website". Three of the five still returned the real file. A crawl with default settings would have noticed nothing.
- The list was not fresh. Our list had last checked these entries a median of 37 minutes before the test. An entry stays on it as alive until its next check fails.
The timeout sets the pace
The Scrapy settings reference defines DOWNLOAD_TIMEOUT as "The amount of time (in secs) that the downloader will wait before timing out", 180 by default. We replayed the 200 requests through entries with the https flag at shorter limits. A crawl sending one request at a time would have fetched 56.7 files per hour at 10 seconds, and 12.7 at the default. The short limit keeps fewer of the slow successes, 28 files instead of 62. It also stops waiting on dead entries and moves on. With thousands of entries on a list, moving on is cheaper than waiting. A new project sends one request at a time to each site, so this is the pace of a crawl of one site, before the delay between requests.
Settings for a free list
# settings.py
DOWNLOAD_TIMEOUT = 20                # the default is 180 seconds
RETRY_TIMES = 10                     # the default is 2; each retry goes to another entry
DOWNLOAD_VERIFY_CERTIFICATES = True  # the default is False
ROBOTSTXT_OBEY = True                # a new project sets this already
CONCURRENT_REQUESTS_PER_DOMAIN = 1   # a new project sets this already
DOWNLOAD_DELAY = 1                   # a new project sets this already

DOWNLOADER_MIDDLEWARES = {
    "myproject.middlewares.FreeProxyMiddleware": 610,
}
- DOWNLOAD_TIMEOUT and RETRY_TIMES. At 20 seconds, 40 of the 200 entries in our test returned the file, so one attempt in five worked. The Scrapy documentation defines RETRY_TIMES as the "Maximum number of times to retry, in addition to the first download". The middleware below sends each retry through another entry.
- DOWNLOAD_VERIFY_CERTIFICATES. The Scrapy security page puts it plainly: "By default Scrapy does not verify the TLS certificate of HTTPS servers". With the setting on, requests with a bad certificate "fail instead of silently succeeding". Through free proxies, this is what turns a swapped certificate into an error.
- The last three. A project made with
scrapy startprojectalready sets them to True, 1 and 1. Without it, Scrapy falls back to False, 8 and 0. A proxy changes where a request comes from, not how hard a site should be hit, so keep them.
Loading the list
# settings.py
import urllib.request

# entries alive on their last check, able to tunnel HTTPS, listed at 5 seconds or less
LIST_URL = "https://hproxy.com/api/proxy-list?format=txt&protocol=https&max_latency_ms=5000"
with urllib.request.urlopen(LIST_URL, timeout=30) as response:
    FREE_PROXIES = response.read().decode().split()
Our free proxy list API returns one address and port per line, with no key and no signup. Two filters help Scrapy:
protocol=httpskeeps entries with the https flag. Within 20 seconds, they returned the file four times as often in our test: 40 of 200, against 5 of 100 without the flag.max_latency_ms=5000keeps entries that answered their last check within 5 seconds. Of the 70 such entries in our test, 20 returned the file within 20 seconds, against 20 of the 130 slower ones.
Leave out recent=true. Our documentation says it "WIDENS the list, it does not freshen it", by adding entries that have gone quiet. Write each entry as http://address:port, even with the https flag. The Scrapy documentation notes: "Usually a proxy URL uses the http:// scheme." Its default handler "supports HTTPS proxies only for HTTP destinations", so an https:// proxy URL would not reach https:// pages.
A middleware that drops dead entries
# middlewares.py
import logging
import random

from scrapy.exceptions import IgnoreRequest

logger = logging.getLogger(__name__)


class FreeProxyMiddleware:
    """Sends each request through a random entry of a free list and drops entries that fail."""

    def __init__(self, proxies):
        self.proxies = set(proxies)

    @classmethod
    def from_crawler(cls, crawler):
        return cls(crawler.settings.getlist("FREE_PROXIES"))

    def process_request(self, request, spider=None):
        if "proxy" in request.meta:
            return None
        if not self.proxies:
            # never let a request go out from your own address
            logger.warning("No free proxies left, dropping %s", request.url)
            raise IgnoreRequest("no free proxies left")
        request.meta["proxy"] = "http://" + random.choice(tuple(self.proxies))
        return None

    def process_exception(self, request, exception, spider=None):
        if isinstance(exception, IgnoreRequest):
            return None
        # the entry failed: forget it, and let the retry go through another one
        failed = request.meta.pop("proxy", "")
        self.proxies.discard(failed.removeprefix("http://"))
        return None
Three details make it work with a free list:
- The order number 610. Scrapy calls
process_request()"in increasing middleware order", so 610 runs before the built-in HttpProxyMiddleware at 750, which applies the proxy. Exceptions travel the other way, from the downloader back toward the engine, soprocess_exception()at 610 runs before the retry middleware at 550. - The
popbefore the retry. The retry middleware sends a copy of the failed request,metaincluded. Without thepop, the retry would go through the same dead entry. With it,process_request()picks a new one. - The empty list. Without the
IgnoreRequest, a request with no entry left would go out without a proxy, from your own address. Scrapy does not log an ignored request, so the middleware logs a warning first.
The spider=None parameters keep the class working on Scrapy versions before 2.14, which pass a spider. Since 2.14, requiring that argument is deprecated. Several guides use the scrapy-rotating-proxies package instead. Its last release on PyPI, 0.6.2, dates from 25 May 2019. For rotation with paid proxies and per-proxy passwords, see how to use proxies with Scrapy.
Check that the spider uses the proxies
# spiders/ipcheck.py
import scrapy


class IpCheckSpider(scrapy.Spider):
    name = "ipcheck"
    start_urls = ["https://httpbin.org/ip"] * 10

    def parse(self, response):
        self.logger.info("left from %s through %s", response.json()["origin"], response.meta.get("proxy"))
Scrapy does not drop the repeated start URLs as duplicates, so this sends ten requests. If each line shows an address other than your own, the proxies are in use. Our free proxy checker tests a single entry by hand, and how to check if a proxy is working covers the tests behind it. A tunnel that fails shows up as a TunnelError, explained in Scrapy TunnelError: could not open CONNECT tunnel.
SOCKS5 entries
The default download handler of Scrapy does not speak SOCKS. Its documentation says: "HttpxDownloadHandler supports SOCKS proxies while other built-in handlers don't." That handler arrived in Scrapy 2.15.0, gained SOCKS support in 2.17.0 and needs the httpx extra. It supports SOCKS5, not SOCKS4, and its documentation calls it "experimental, and not yet recommended for production environments". To try it:
# settings.py, after: pip install "scrapy[httpx]"
DOWNLOAD_HANDLERS = {
    "http": "scrapy.core.downloader.handlers._httpx.HttpxDownloadHandler",
    "https": "scrapy.core.downloader.handlers._httpx.HttpxDownloadHandler",
}
Then load the list with protocol=socks5, and write socks5:// instead of http:// in both places in the middleware. Keep DOWNLOAD_VERIFY_CERTIFICATES on, since this handler reads it too. In an earlier test on 28 September 2026, 15 of 85 free SOCKS5 proxies that finished an HTTPS handshake with our site handed back a forged certificate. The details are in are free proxies safe.
What no setting fixes
- Plain http:// pages. Without TLS, the proxy can read and change the whole exchange. The Scrapy security page says that such data "travels in plain text and can be read or modified by anyone on the network path".
- Logins and personal data. Never send a password, a session cookie or personal details through a free proxy. In 5 of the 89 TLS sessions of our test, the certificate was not ours.
- The rules of the site. A free proxy changes the address a request comes from, not what the site allows. Keep ROBOTSTXT_OBEY on, read the terms of the site, and stop where they forbid automated access.
When free is not enough
For a crawl that has to finish on time, such as checking your own product pages from other countries, a residential proxy is the better tool. Its address belongs to a home connection, and it stays up while you work. Ours start at $0.44/GB, pay as you go, and purchased traffic has no scheduled expiry date. The choices for a paid crawl, from proxy type to pool size, are in proxies for Scrapy.
The plain answer
Free proxies can feed Scrapy, slowly. In our test of 300, fewer than a third returned the file, about half never answered, and five swapped the certificate. Set DOWNLOAD_TIMEOUT to 20 seconds, RETRY_TIMES to 10 and DOWNLOAD_VERIFY_CERTIFICATES to True. Load entries with the https flag, drop every entry that fails, and keep logins and personal data off free proxies.
How we measured
On 28 September 2026 between 12:56 and 12:59 UTC, a script on our Linux server in the United States took a random sample from our free list API: 200 entries with the https flag and 100 with only the http flag. All were alive on their last check. Through each, it opened a CONNECT tunnel to our site, ran TLS and requested /robots.txt with the user agent and Accept headers of a default Scrapy request. Each request had 180 seconds in all. Three direct requests gave the real file and certificate to compare against. The rates at shorter limits replay the same timings. We store no proxy addresses, and every time is in UTC.
Sources
- Scrapy documentation, version 2.19.0 of 10 September 2026, read 28 September 2026: Downloader Middleware, Settings, Download handlers, Security and Release notes.
- IETF, RFC 9110: HTTP Semantics, June 2022, section 9.3.6 on CONNECT.
- The Linux kernel documentation: IP Sysctl, on tcp_syn_retries.
- mitmproxy documentation: About Certificates.
- HProxy documentation: the free proxy list API and the proxy checker API, read 28 September 2026.