Free proxies can do small scraping jobs on public pages, as long as the scraper expects most requests to fail and moves on quickly. A scraper sends many requests through a proxy, not one, so we tested that on 28 September 2026 at 14:09 UTC. We took 250 free proxies that our list showed as alive and sent 20 requests in a row through each, to our own site, one second apart. 1,277 of the 5,000 requests got an answer. 13 proxies answered all 20, and 79 answered none.
This page covers what the test showed, what our other tests found, and how to scrape with free proxies without wasting a day or your data.
What 250 free proxies did with 20 requests each
Each request opened a new connection through the proxy, as a scraper without a session does, and asked for our robots.txt over HTTPS. For an HTTP proxy, that means a tunnel with the CONNECT method, which RFC 9110 describes as a request to "establish a tunnel to the destination origin server". A request counted only if our real file came back under our real certificate within 20 seconds.
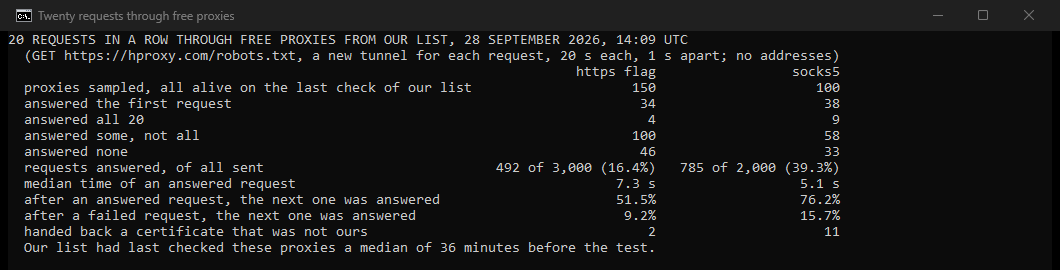
- Most proxies came and went. 158 of the 250 answered some requests but not all. Only 13 answered all 20, and 79 answered none, although all were alive on the last check of our list.
- A proxy that just answered is worth keeping. After an answered request, the next one through the same proxy was answered 51.5 percent of the time for entries with the https flag, and 76.2 percent for SOCKS5 entries.
- A proxy that just failed is worth dropping. After a failed request, the next one was answered only 9.2 and 15.7 percent of the time. 31 proxies answered within their first five requests and none of their last five.
- Most failures were silence. 79.6 percent of the failed requests simply got no answer within 20 seconds.
- Some certificates were not ours. 13 proxies handed back a certificate that was not the one of our site: 11 SOCKS5 entries on nearly every request, and 2 HTTP entries on 8 and 11 of their 20.
What our other tests showed
The same day and the day before, we ran three more tests through free proxies from our list:
- One request, as Scrapy sends it. At 12:56 UTC, 83 of 300 entries returned our robots.txt within 180 seconds, and 146 never accepted the connection. Free proxies for Scrapy has the settings that follow.
- A whole page, as Chrome loads it. At 13:37 UTC, 111 of 300 delivered one of our pages with its 25 files, at a median of about 23 seconds. Directly, the page took 0.4 to 2.0 seconds. Free proxies for Selenium has the browser setup.
- Real websites. On 27 September, 116 of 700 loaded the real page of a game or app website within 20 seconds.
Over a longer span, those that worked and then stopped lasted a median 10 days, counting only addresses with fewer than 20 of them, without Amazon's networks or one June evening when our checker failed (measured 2026-09-28). In our test, 27 proxies answered none of their first five requests and some of their last five. A free proxy answers some of the time, and a scraper has to live with that.
How to scrape with free proxies
import random
import urllib.request

import requests

# entries alive on their last check that can tunnel HTTPS
LIST_URL = "https://hproxy.com/api/proxy-list?format=txt&protocol=https"
with urllib.request.urlopen(LIST_URL, timeout=30) as response:
    entries = response.read().decode().split()

current = None


def fetch(url, attempts=10):
    """Keeps an entry while it answers and takes a new one after a failure."""
    global current
    for _ in range(attempts):
        if current is None:
            if not entries:
                raise RuntimeError("no free proxies left")
            current = entries.pop(random.randrange(len(entries)))
        proxy = f"http://{current}"
        try:
            # certificate checks stay on, the default of requests
            return requests.get(url, proxies={"http": proxy, "https": proxy}, timeout=20)
        except requests.exceptions.RequestException:
            current = None  # after a failure, the same entry rarely answered the next request
    raise RuntimeError(f"no entry answered in {attempts} attempts")
Our free proxy list API returns one address and port per line, with no key and no signup. Six rules follow from the tests:
- Take entries that can tunnel HTTPS.
protocol=httpsgives the entries our checker saw open a CONNECT tunnel. Write them withhttp://, the way the requests documentation writes its own example for HTTPS traffic. - Set a timeout. The requests documentation says that "Nearly all production code should use this parameter in nearly all requests", since without one a program can "hang indefinitely". Around 20 seconds fits a request, and around 30 seconds a whole page in a browser.
- Keep what answers, drop what fails. The code keeps an entry after an answer and takes a new one after any failure, since the numbers above favour it.
- Keep certificate checks on. Requests checks the certificate of every HTTPS site by default, "just like a web browser", in the words of its documentation. A certificate that fails the check stops the request, which is what a scraper needs when a proxy hands back the wrong one. Never pass
verify=False. - Slow down when asked. RFC 6585 defines status 429 for a client that "has sent too many requests in a given amount of time", and says the answer "MAY include a Retry-After header". Wait at least that long.
- Follow robots.txt. RFC 9309 describes its rules as ones "that crawlers are requested to honor when accessing URIs". A proxy changes the address a request comes from, not what the site allows.
For SOCKS5 entries, load the list with protocol=socks5, install requests[socks], and write socks5h://. The requests documentation explains that plain socks5 resolves names on your own computer, while socks5h lets the proxy resolve them. In our test, SOCKS5 entries answered more often: 785 of 2,000 requests, against 492 of 3,000 for entries with the https flag. Still, 11 of the 100 handed back a certificate that was not ours.
Where free proxies fit
- Public pages, small jobs. A few hundred pages from a site that allows it, where a failed request costs a retry and nothing else.
- Tests. Checking that your scraper routes through a proxy at all, before a paid pool replaces the list.
- A look from another place. Checking a public page from another network or country.
What no setting fixes
- Logins and personal data. Never send a password, a session cookie or personal details through a free proxy. In our test, 13 of 250 handed back a certificate that was not ours.
- The rules of the site. Read the terms of the site you scrape, and stop where they forbid automated access. No proxy makes that allowed.
- A deadline. With about one request in four answered, a free list cannot promise when a job ends.
When free is not enough
For a scrape that has to finish on time, a residential proxy is the better tool. Its address belongs to a home connection, and it stays up while you work. Ours start at $0.44/GB, pay as you go, and purchased traffic has no scheduled expiry date. The choices for a paid setup, from proxy type to rotation, are in proxies for web scraping.
The plain answer
Free proxies can carry a small scrape of public pages. In our test of 250, about one request in four got an answer, only 13 answered 20 requests in a row, and 13 handed back a certificate that was not ours. Set a timeout of about 20 seconds, keep an entry while it answers, drop it after a failure, keep certificate checks on, and never send a login through a free proxy.
How we measured
On 28 September 2026 between 14:09 and 14:16 UTC, a script on our Linux server in the United States took a random sample from our free list API. It took 150 entries with the https flag and 100 SOCKS5 entries, all alive on their last check. Through each, it sent 20 requests for our robots.txt, one second apart, each over a new tunnel with TLS and each allowed 20 seconds. Three direct requests gave the file and the certificate to compare against. The other tests ran from the same server. We store no proxy addresses, and every time is in UTC.
Sources
- The requests documentation: Advanced Usage and Quickstart, read 28 September 2026.
- IETF, RFC 9110: HTTP Semantics, June 2022, section 9.3.6 on CONNECT.
- IETF, RFC 6585: Additional HTTP Status Codes, April 2012, section 4 on 429.
- IETF, RFC 9309: Robots Exclusion Protocol, September 2022.
- HProxy documentation: the free proxy list API, read 28 September 2026.